Start with the pain — what breaks and why
Lines stop. Motors sing odd. Sensors drift. That’s the sort of trouble that eats hours and patience on a Monday morning when you’ve got orders to meet. I’ve been out on floors fixing conveyor clutches, swapping failed PLC modules and re-zeroing instruments for years, and the same problems keep showing up around manufacturing automation technology and industrial automation technology. You don’t need fancy reports to see it — you need a checklist that stops small things from turning into big stoppages. Hannover Messe shows the tech; the plant still needs hands that know how to keep it running.
Daily checks that pay off
Do these every shift. They take minutes and dodge hours of trouble.- Walk the line: listen for odd noises, watch for belt tracking and leaks.- Check alarms: confirm alarm summaries and clear resolved events after noting them.- Verify vision and presence sensors: a dirty lens or bumped bracket causes false rejects.- Confirm safety interlocks: doors, light curtains and e-stops must respond every time.- Quick backups: copy current PLC logic and HMI screens to a local drive before any change.
Weekly and monthly work that prevents surprises
Set fixed days for hands-on checks.- Tighten and inspect mechanical fastenings; vibration loosens things faster than you think.- Clean cooling fans, heat sinks and filter screens; heat kills electronics.- Validate IO points: use a simple multimeter or a handheld test rig to ensure sensors read correctly.- Review trending for drift: scan a week of tag history to spot creeping offsets early.- Update spare lists: replace parts used that week and reorder essentials before stock runs low.
Quarterly tasks that catch slow failures
Do deeper dives on a schedule.- Calibrate critical sensors (flow, pressure, temperature) and log calibration certificates.- Exercise backups and failovers: simulate a controller or network failure and watch the recovery.- Check battery-backed memory and RTC batteries in controllers and HMIs.- Inspect cable runs and terminations for corrosion, chafing and water ingress.
Common mistakes that sneak up on you
Watch for these traps; they look small until they aren’t.- Treating a symptom instead of finding the root cause — fixing alarms without tracing why they happened.- Skipping documentation — when someone leaves, undocumented tweaks become permanent risks.- Over-relying on canned vendors’ settings — they’re starting points, not the final tune for your plant.- Hoarding spares in a desk drawer — spares should be labeled, tested yearly and stored properly.
When to call in the specialist
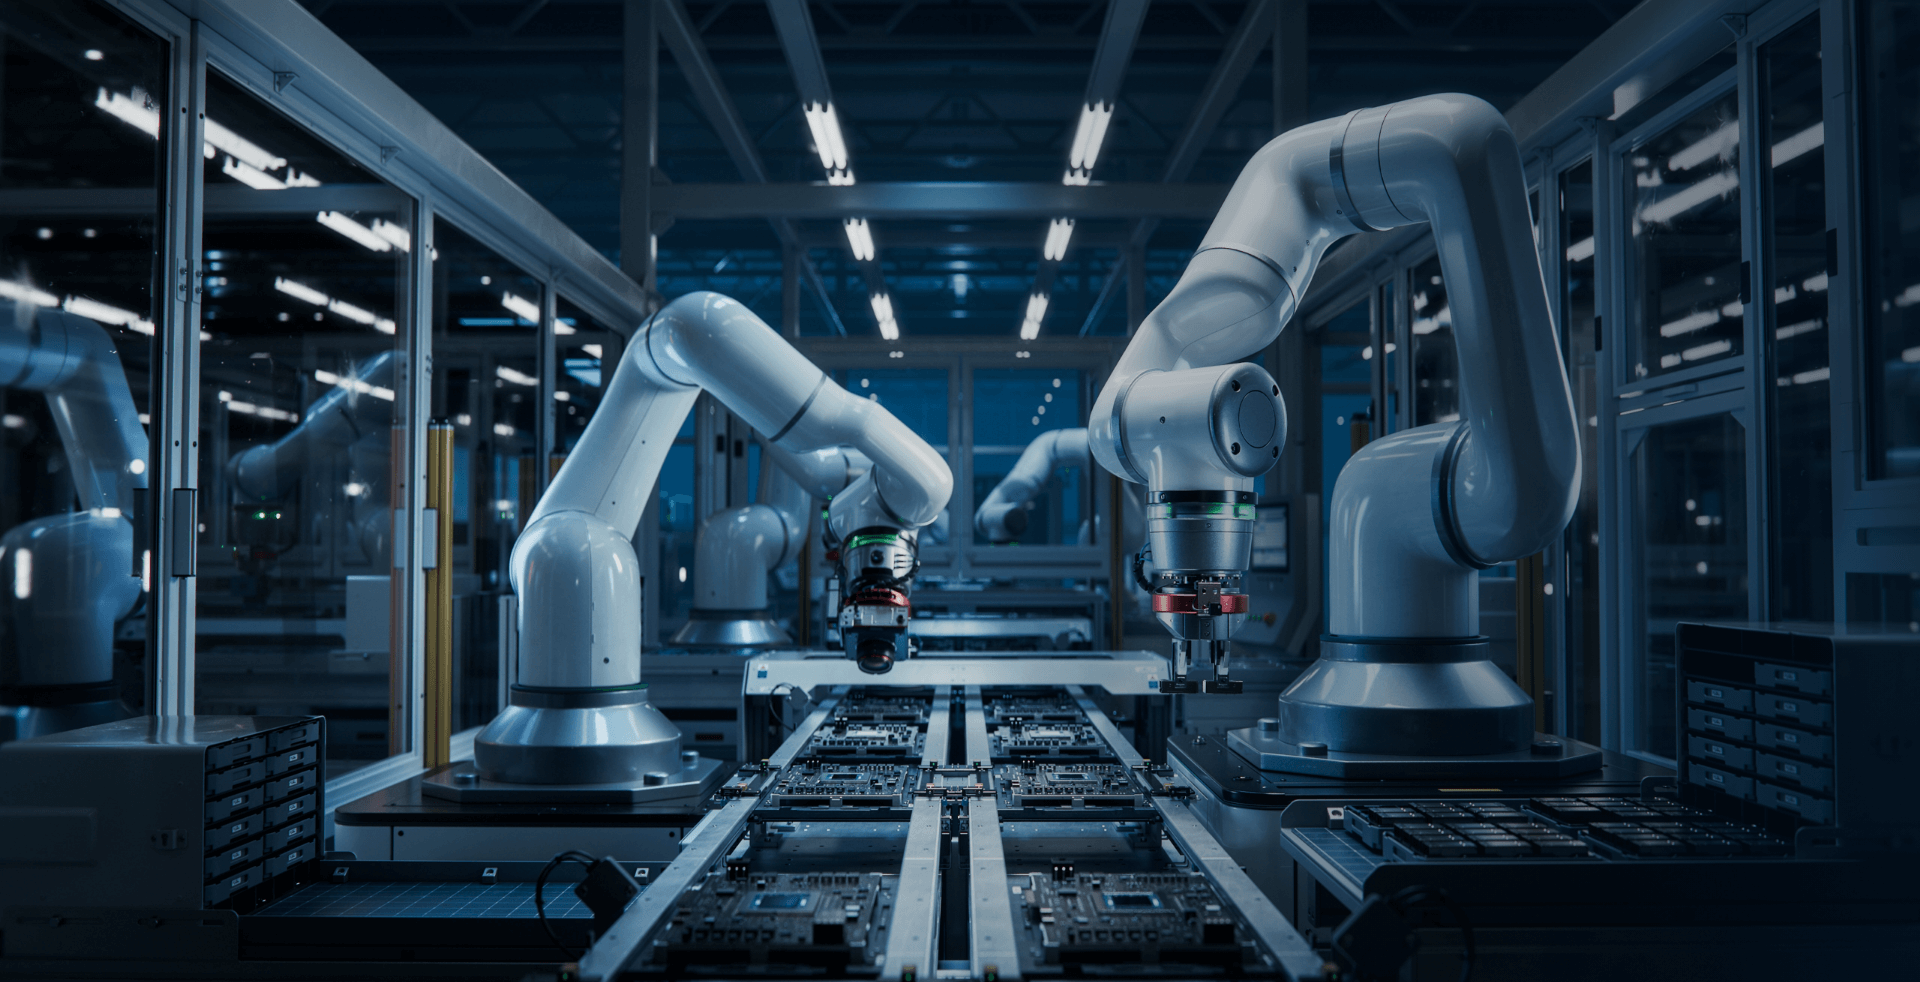
Handle small fixes yourself; call a specialist when signs look structural.- Repeated unexplained PLC reboots, unexplained network partitions or firmware corruption.- System-wide timing errors, inconsistent I/O across multiple cabinets, or safety logic faults.- Before major firmware upgrades or architecture changes, get an experienced integrator to review the plan.A clear failure mode and effect note will make the specialist’s work faster and cheaper.
Keeping records that actually help
Good logs aren’t for show; they’re your next rescue plan.- Timestamped entries for changes and incidents.- Calibration certs attached to the asset record.- Simple diagrams showing who did what and when.These make troubleshooting faster and reduce repeated mistakes.
Final word, plain and useful
Keep checks short, regular and recorded. Prioritize the fixes that stop repeat failures and make sure someone owns the routine. Field experience matters — steady hands, clear notes, and a small stash of tested spares beat panic troubleshooting every time. Teams that do this work with common sense and proper records often partner with suppliers who understand both the hardware and the floor; that’s why local support from FHS fits naturally into a plant’s steady plan.